How to Ask Omni AI About Images and Documents
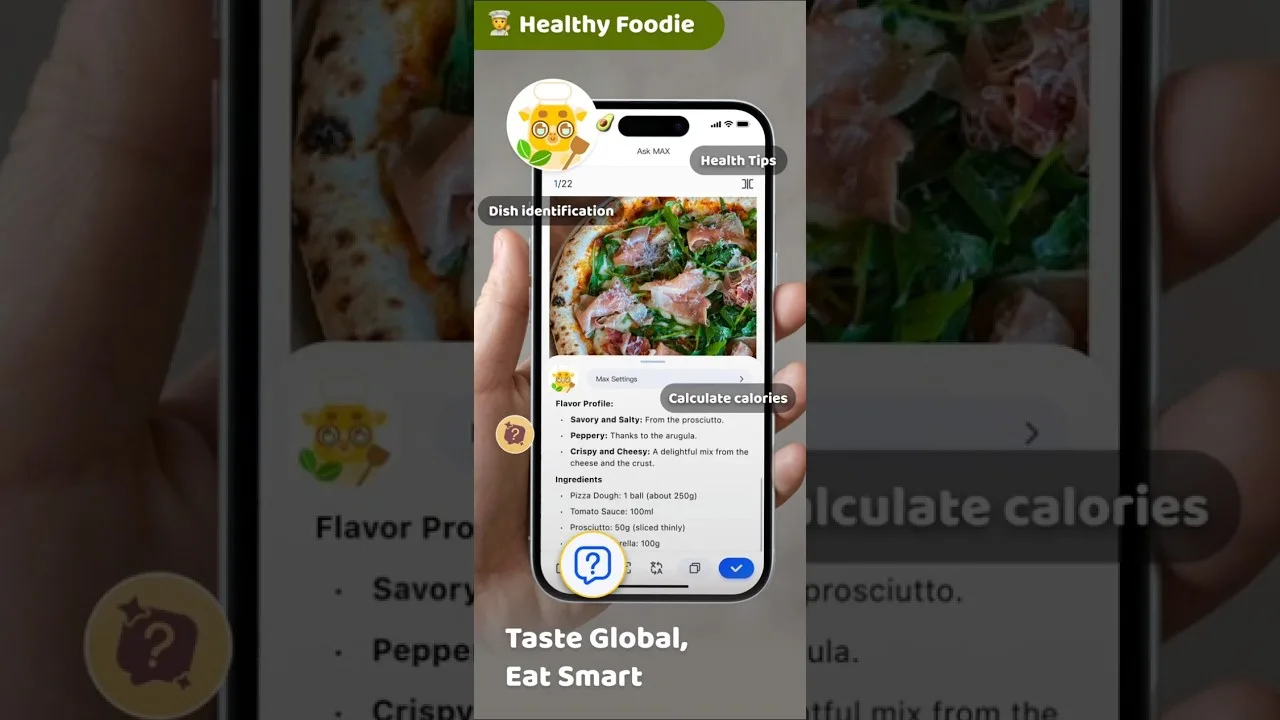
An assistant that can see changes what you can ask: not just 'what is this plant' but 'does this contract clause match the email', 'what does this error screen actually want', 'read this handwritten page'. the Omni AI mobile app can take images and documents as inputs to its answers, and this guide teaches the craft — preparing inputs the vision can read, asking questions that get precise answers, and reading those answers with the scepticism any powerful sense deserves.
Vision is a sense, not an oracle. It reads what is legible, reasons over what it reads, and errs in characteristic ways this guide will name, so you can catch them.
Start with one real artefact: the letter you are puzzling over, the photo whose contents you need listed, the screenshot that has been sitting in your gallery as an unsolved problem.
What Vision Handles Well
Description, identification of common objects and scenes, reading printed and clearly written text, summarising documents, comparing two images, and answering specific questions about contents — these are the strong suits. A document's gist, a chart's trend, a sign's instruction: reliable territory when the input is clear.
Ask one question at a time and let follow-ups do the deepening. Compound questions ('what is this, when was it taken, is it valuable, and translate the sign') receive averaged answers; a conversation receives considered ones.
Prepare the Input Like Evidence
Photograph documents flat, square-on, in even light, filling the frame; screenshots beat photographs of screens at every distance. Crop to the relevant page or region rather than sending a desk's entire archaeology and hoping the assistant finds the paragraph that matters.
For long documents, feed in sections and ask section questions, then request the synthesis. Vision over a dense forty-page scan in one gulp produces the summary of a skim; sectional reading produces the summary of a study. The same preparation discipline powers the prompt craft in the Omni AI prompt writing guide — material first, questions second.
Ask Questions With Addresses
Point inside the document: 'in the second paragraph', 'the figure at the bottom right', 'the clause about termination'. Addressed questions return addressed answers, and addressed answers can be verified with your own eyes in seconds — which is the entire safety system for vision work.
Ask for quotations where exactness matters. A model asked to quote the sentence it is interpreting shows its working; a model asked to paraphrase freely can drift while sounding identical.
Read Results Critically
Vision errors have signatures: confident misreadings of small or degraded text, invented details in busy regions, plausible completions where the image was ambiguous. Verify names, numbers, and dates against the image with your own eyes before using them anywhere consequential.
Where the assistant expresses certainty about something you can see is unclear, trust your eyes and say so — a corrected second reading is often markedly better, because the correction directs the sense to the right region.
Documents With Consequences
Contracts, medical letters, official forms: use the assistant to understand, to summarise, to prepare questions for the professional — not as the professional. Its reading is a first pass by a brilliant amateur, and documents with consequences deserve the second pass by the accountable human expert.
Redact before you share onward. The assistant's summary of a document can travel without the document's sensitive details, and choosing the summary as the travelling artefact is a privacy habit worth automating in yourself.
Privacy of What You Show
Images and documents you submit are processed to be answered, under the provider's current terms — read them once and show material accordingly. Your own documents for your own understanding are the natural use; other people's documents, children's images, and workplace material deserve the consent and policy checks any sharing deserves.
The privacy settings and habits that govern all of this are collected in Omni AI privacy and chat history settings, which this page assumes as its foundation.
A Working Session, Start to Finish
Assemble the method: choose the artefact, prepare it cleanly, ask one addressed question, verify against the image, follow up twice, then request the summary or extraction you actually needed — a list, a translation, a set of questions for a human expert.
File the useful outputs with the artefact, not in the chat's weather. Vision sessions produce small, valuable extractions, and extractions deserve a home where future you can find them without re-asking.
Clear input, addressed questions, quoted evidence, verified numbers: vision used that way is a second pair of tireless eyes. Used casually, it is a confident narrator standing between you and your own documents.
Begin with the screenshot that has puzzled you longest. It has been waiting for exactly this conversation.
Finally, treat each verified extraction as training data for your own eye: after a few dozen documents checked line by line, you will start spotting the model's characteristic wobbles — the digit it favours when unsure, the name style it normalises — and your verification will sharpen from general care into targeted suspicion of exactly the right details. That is the mature, durable, everyday, working form of the skill this guide teaches: not distrust, and certainly not faith, but a working knowledge of where this particular reader's eyes blur, applied every time the reading matters.
Related Articles
How to Update Omni AI to the Latest Version
Update Omni AI on Android in place: check the version, keep your chats and settings, verify with a familiar question, and fix stalled updates.
Read More →
Omni AI Prompt Writing Guide: Ask Better, Get Better
Write prompts Omni AI answers well: context, format, examples, and step-by-step requests, plus the iteration habit that sharpens every answer.
Read More →
Writing and Essays With Omni AI: Draft, Structure, Polish
Use Omni AI for writing without losing your voice: outlines, drafts in your material, editing passes, and keeping authorship honestly yours.
Read More →
Omni AI for Students and Homework: Learn Faster, Honestly
Use Omni AI as a study partner: explanations at your level, practice questions, essay structure help, and the honesty rules that keep learning real.
Read More →
Omni AI Voice Chat Tips: Talk Naturally, Get More
Use voice chat in Omni AI well: setup, natural pacing, dictating long inputs, hands-free uses, and fixing recognition that keeps misunderstanding you.
Read More →
Coding Help With Omni AI: Learn, Debug, and Build
Use Omni AI for coding help: explain errors, learn concepts by example, debug in steps, and review generated code like a professional would.
Read More →